Trulyscribe

Author name: Editorial Team

can-ai-transcripts-increase-organic-traffic-case-studies
SEO, Case Studies, Content Strategy

Can AI Transcripts Increase Organic Traffic? (With Case Studies)

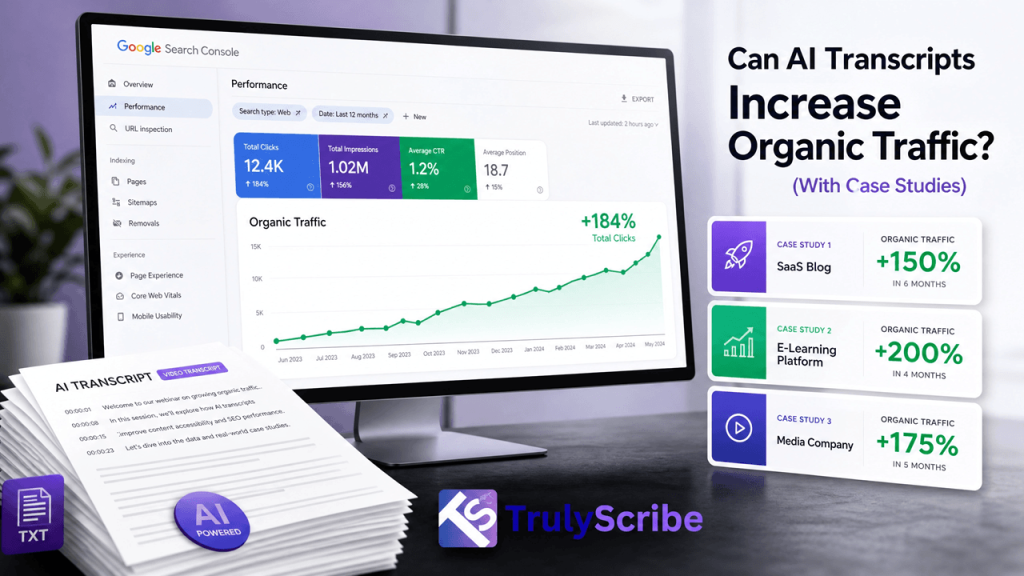
It’s a reasonable question to be skeptical about. Adding a wall of text under a podcast player or video embed sounds more like an accessibility checkbox than a growth strategy. But this is one of the rare SEO questions with an actual, measurable paper trail behind it. Organizations have been publishing transcripts and tracking the traffic impact for well over a decade, and the results are consistent enough to draw real conclusions from. This article looks at what transcripts actually do for organic traffic, walks through documented case studies, and lays out how to apply the same approach using modern AI transcription. Why Transcripts Affect Organic Traffic in the First Place Search engines rank text. An audio or video file, on its own, gives a crawler almost nothing to work with beyond a title, a description, and whatever metadata has been added by hand. That’s a tiny fraction of what’s actually said in a 30-minute podcast episode or a 10-minute product demo. A transcript changes that completely. It converts everything spoken in the recording into indexable text, including the specific phrases, questions, and long-tail language a real listener used — language that’s often far more specific and conversational than what shows up in a polished show note or video description. That specificity matters because long-tail, conversational phrases are exactly what a meaningful share of search queries look like, especially as voice search and question-based queries have grown. Transcripts also tend to be long. A single episode can produce several thousand words of unique, topically focused text, which gives a page far more surface area to rank for related searches than a short summary ever could. And because transcripts are often the most detailed, quotable version of the content available, they tend to attract more inbound links and citations than the audio or video alone — which reinforces search authority over time. Case Study 1: This American Life This American Life — Full Archive Transcription+4.18% unique visitors · +6.68% organic search visitors · +3.89% inbound linksOne of the most cited transcript SEO studies comes from the public radio program This American Life, which transcribed its entire audio archive and published the transcripts on its website between April and October 2011. A case study conducted afterward found that unique visitors to the site increased, with the increase in visitors arriving specifically through organic search outpacing overall visitor growth. The study also found that transcript pages attracted a meaningful share of new inbound links — hundreds of external links pointed directly to transcript pages, showing that the text itself, not just the audio, was being referenced and cited elsewhere on the web.Source: 3Play Media case study, “This American Life: Boosting Podcast SEO with Transcription.” What makes this case study useful is its scope: it wasn’t a single episode or a short test, but an entire archive transcribed and tracked over time, which is closer to what most creators or brands would realistically do. Case Study 2: Davis Phinney Foundation (via Moz) Davis Phinney Foundation — Transcripts Added to Podcast Pages+15% organic traffic · +50% keyword rankings (within 3 months)SEO research firm Moz studied the impact of adding transcripts to podcast episode pages for the Davis Phinney Foundation, a health-focused nonprofit. Within just three months of publishing transcripts alongside episodes, the site saw a notable increase in organic traffic, along with a substantial lift in the number of keywords the site ranked for. The relatively short three-month window is notable, since it suggests transcripts can start contributing to search visibility well before the kind of long-term compounding effect SEO strategies often require to show results.Source: Moz research, cited via multiple podcast SEO industry reports. This case is a useful counterpoint to the idea that transcript SEO only pays off over years. A meaningful lift within a single quarter suggests the mechanism — more indexable, specific text — starts working almost as soon as it’s published and crawled. Case Study 3: A Composite Small-Business Scenario The following is an illustrative, composite scenario built from common patterns reported across podcast and content-marketing SEO case studies, rather than a single tracked company. It’s included to show how the mechanism plays out at a smaller scale than a national radio program. Illustrative Example — A Niche B2B PodcastPattern seen across smaller, niche podcasts adding transcriptsA small B2B podcast in a specialized industry (say, commercial insurance or veterinary supply) typically has limited domain authority and can’t compete head-to-head with large publishers on broad keywords. What smaller shows in this position consistently report after adding transcripts is traffic growth concentrated in long-tail, highly specific searches — phrases only mentioned once, in passing, by a guest during an interview. Because larger competitors rarely cover that exact phrase in text form, a transcript page can rank for it with relatively little competition, even on a lower-authority domain. Over dozens of episodes, this compounds into a meaningful stream of niche, high-intent organic traffic that the audio alone was never going to capture.Illustrative pattern, not a single verified case. What These Case Studies Have in Common How to Apply This With Modern AI Transcription The case studies above predate today’s AI transcription tools, which is worth noting: This American Life’s 2011 project and Moz’s early research relied on more manual or expensive transcription processes at a time when producing accurate transcripts at scale was a significant undertaking. That constraint has largely disappeared. Modern AI transcription tools can process an hour of audio or video in minutes, at a fraction of the historical cost, which means the traffic gains documented in these studies are now realistically achievable for far smaller creators and businesses — not just national media organizations with production budgets to match. A Few Realistic Caveats Transcripts aren’t a guaranteed traffic multiplier for every site. A few factors shape how much impact they’ll actually have: Final Thoughts The evidence here isn’t anecdotal — it’s measured, documented, and consistent across more than a decade of case studies, from This American Life’s full-archive project
transcribing-videos-for-geo-complete-guide
SEO, AI Tools, Video Marketing

Transcribing Videos for GEO (Generative Engine Optimization): Complete Guide

Generative Engine Optimization, or GEO, is the practice of shaping content so it gets picked up, understood, and cited by AI systems like ChatGPT, Perplexity, Google AI Overviews, and Copilot — rather than just ranked in a traditional list of search results. For anyone producing video content, GEO comes with a specific, unavoidable requirement: the video needs to exist as text somewhere, because generative AI systems work with language, not footage. Transcription is the bridge between a video sitting in your library and that same video showing up as a cited source in an AI-generated answer. This guide walks through exactly how to transcribe and structure video content so it performs well under GEO, step by step. What GEO Is, and Why It Treats Video Differently Than SEO Does Traditional SEO optimizes for ranking algorithms that crawl pages, weigh backlinks, and return a list of links for a person to click through. Video SEO within that world has always leaned heavily on titles, descriptions, thumbnails, and watch-time signals, because the algorithm was never really “reading” the video itself. GEO works differently because generative engines don’t return a list of links — they generate a direct answer, often with a citation, by pulling from text they can process and understand. A generative engine can’t watch your video, follow your presenter’s tone, or catch the nuance in a live demo. It can only work with what’s written down. That means a video with no transcript is, from a generative engine’s point of view, mostly invisible — no matter how good the content inside it actually is. This is why transcription sits at the center of any serious GEO strategy for video. It’s not an accessibility nice-to-have anymore; it’s the mechanism that makes video content eligible to be read, chunked, matched to a query, and cited in the first place. How Generative Engines Process Transcribed Video Content Step 1: Text becomes available for retrieval Once a video is transcribed and that transcript is published as text — on a webpage, in a knowledge base, or through a connected content source — it becomes something a generative engine can retrieve. Before this step, the underlying video content simply doesn’t exist in a form these systems can use. Step 2: The transcript is broken into chunks Generative engines typically don’t evaluate an entire page as one unit. They split content into smaller passages and assess each one for relevance to a specific query. A transcript, full of complete spoken statements and natural explanations, tends to chunk well — each section of dialogue often stands on its own as a clear, self-contained answer to a plausible question. Step 3: Chunks are matched against a person’s question When someone asks a generative engine something like “what’s the difference between X and Y” or “how do I fix Z,” the system searches available content for the passages most likely to answer accurately. A well-transcribed explainer video, tutorial, or expert interview often contains exactly this kind of directly responsive language, since spoken explanations tend to be phrased the way people actually ask questions. Step 4: The best match gets surfaced, often with a citation If your transcript contains the clearest, most accurate, best-structured answer to the question being asked, it stands a real chance of being the source the generative engine pulls from and cites. This is the GEO equivalent of a featured snippet or a page-one ranking — visibility inside the answer itself, not just a link beside it. A Step-by-Step Workflow for Transcribing Video for GEO What Makes a Transcript Genuinely GEO-Friendly Publishing any transcript is better than publishing none, but a few specific qualities separate a transcript that performs well under GEO from one that technically exists but rarely gets surfaced. None of these qualities require re-recording anything. They’re almost entirely a function of how the transcript is generated, lightly edited, and structured after the fact — which is why the transcription and formatting step deserves more attention in a GEO strategy than it typically gets. Common Mistakes When Transcribing Video for GEO Why This Matters More as Video Content Keeps Growing Video has become one of the primary ways expertise gets shared — through webinars, product demos, conference talks, and long-form interviews. Most of that content still lives exclusively as video, which means a large and growing share of the internet’s most substantive, specific expertise is currently invisible to generative engines. That gap is exactly the opportunity GEO-focused transcription addresses: instead of competing for visibility by producing more content, it makes existing, high-value video content newly eligible to be found and cited, often with relatively little additional work. As generative engines continue to lean more heavily on retrieval and citation, the advantage will likely keep compounding for creators and brands that treat transcription as a standard step in their publishing process, rather than an afterthought reserved for accessibility compliance. Final Thoughts GEO doesn’t change what makes video content valuable — clear explanations, specific expertise, and honest answers to real questions still matter as much as ever. What it changes is how that value gets discovered. A generative engine can’t watch a video, but it can read a transcript, and a well-structured, accurate transcript is what turns an hour of expertise sitting in a video file into dozens of citable answers a generative engine can actually find. Running video content through an accurate transcription tool like TrulyScribe, then publishing the result with clear structure, timestamps, and speaker labels, is a straightforward way to make sure the expertise already captured on camera doesn’t stay invisible to the tools more and more people are using to search. Frequently Asked Questions

ai-transcripts-rank-chatgpt-ai-search
SEO, AI Tools, Content Strategy

How AI Transcripts Help Your Content Rank in ChatGPT & AI Search

Search is changing shape. People still type questions into a search bar, but a growing share of them now ask ChatGPT, Google AI Overviews, Perplexity, or Copilot instead — and expect a direct answer, not a page of blue links. For creators sitting on hours of podcasts, webinars, interviews, and video content, this shift creates a quiet but real problem: if that content only exists as audio or video, AI systems can’t read it, quote it, or cite it. An AI transcript is what turns a locked audio file into content an AI engine can actually find, understand, and reference — and it may be one of the highest-leverage, lowest-effort SEO moves available in 2026. Why AI Search Changes the Rules for Audio and Video Content Traditional search engines have always struggled to “read” audio and video the way they read text. A podcast episode or a recorded webinar might rank for its title, but the actual substance — the specific advice, the exact numbers mentioned, the quotable insight at minute 14 — stays invisible to a crawler. Search engines have partially compensated with metadata, closed captions, and manual show notes, but none of that captures the full depth of what was actually said. AI search tools go a step further than traditional crawling. Systems like ChatGPT with browsing, Google’s AI Overviews, and Perplexity don’t just index a page — they read it, break it into semantic chunks, and use those chunks to generate a direct answer to a person’s question. That answer often includes a citation or a direct quote pulled from the source. For a chunk of your content to be selected and cited, it has to exist as clear, well-structured text in the first place. Audio and video, however valuable the content inside them, simply aren’t part of that process unless they’ve been transcribed. This is the core shift: in classic SEO, a video could rank on the strength of its title, thumbnail, and surrounding page content. In AI search, an AI model needs to be able to extract a specific, accurate statement from your content to answer a specific, narrow question. A transcript is what makes that extraction possible. What Makes AI Transcripts Valuable for AI Search Specifically Not all transcription is created equal when the goal is AI visibility rather than just accessibility. A few properties matter more than others. Put simply, a transcript doesn’t just make audio “accessible.” It turns a single recording into a long, naturally written, topically deep piece of text — exactly the kind of content AI search systems are built to extract answers from. How the Process Actually Works 1. AI models retrieve and read text-based content Whether through live browsing, a connected search index, or a retrieval system built into the AI product, these tools work primarily with text. Some can process video or audio directly in limited cases, but the reliable, consistent path to being read is a clean, well-formatted transcript published on a page the AI can access. 2. Content gets broken into chunks Rather than treating a page as one block, AI search systems typically split content into smaller passages — often a few sentences to a paragraph — and evaluate each chunk on its own for relevance to a given question. This is why a long, meandering video description performs worse than a transcript: a transcript naturally contains many self-contained, well-formed statements that work well as individual chunks. 3. Relevant chunks get matched to a query When someone asks an AI assistant a question, the system searches its available content for the passages most likely to answer it accurately, then either summarizes or directly quotes the strongest match. A transcript increases the odds that your content contains the exact phrasing, explanation, or data point the system is looking for. 4. The best-matching source gets cited Many AI search products now show a citation or source link alongside their answer. Being the source behind that citation is the AI-search equivalent of ranking on page one — it drives visibility, brand recognition, and increasingly, referral traffic, since curious users often click through to verify or learn more. This entire chain breaks down at step one if there’s no text to retrieve. A brilliant, highly specific answer buried in a video that’s never transcribed is invisible to this whole system, no matter how good the content actually is. Turning Transcripts Into AI-Search-Ready Content Publishing a raw transcript is a good start, but a few practices make transcripts significantly more effective for AI visibility. This is also where the quality of the transcription itself matters more than it might seem. A transcript full of misheard words, missing punctuation, or garbled speaker attribution isn’t just harder for a human to read — it’s a weaker, less reliable source for an AI system trying to extract an accurate answer. This is precisely the kind of use case TrulyScribe is built for: fast, accurate AI transcription with automatic speaker labeling, timestamps, and support for a wide range of languages, producing a clean transcript that’s ready to publish rather than needing hours of manual correction. For anyone sitting on a backlog of podcast episodes, webinars, or interviews, running that content through a reliable transcription tool and publishing the result is one of the more straightforward ways to make existing content newly visible to AI search. Who Benefits Most From This The common thread is that none of these groups need to create new content to benefit. The insight already exists in a recording; transcription is what makes it visible to the systems increasingly standing between that content and the people searching for it. A Simple Starting Workflow For anyone looking to act on this without overhauling an entire content strategy, a lightweight starting workflow looks like this: identify the handful of audio or video pieces that contain the most specific, valuable insight — a flagship podcast episode, a well-attended webinar, a detailed expert interview. Run each through an AI transcription tool to

ai-transcription-voice-notes-personal-productivity-2026
Productivity, AI Tools, Transcription

From Voice Notes to Actionable Insights: AI Transcription for Personal Productivity (2026)

Your phone’s voice memo app is quietly becoming the most cluttered drawer in your digital life. Half-finished ideas, meeting recaps, grocery lists muttered on the way to the car, a brilliant thought you had in the shower — all sitting there as untouched audio files you will “listen to later.” In 2026, AI transcription tools have finally closed the gap between recording a thought and doing something useful with it. This guide walks through how modern AI transcription turns voice notes into searchable text, structured tasks, and real insight — and how to build a voice-first productivity system around it. Why Voice Notes Alone Aren’t Enough Anymore Voice notes are the fastest way to capture a thought. Talking is roughly three times faster than typing, which is exactly why so many of us default to hitting record instead of opening a notes app. The problem isn’t capture — it’s retrieval. An audio file is a black box. You can’t skim it, search it, copy a line from it into an email, or ask it to remind you of a deadline you mentioned in passing. This is what productivity researchers sometimes call the “capture-to-action gap.” You record the idea, then the idea sits in audio purgatory until you either forget about it or spend fifteen minutes re-listening to a two-minute clip trying to find the one sentence that mattered. Multiply that across dozens of voice notes a week, and the very tool meant to save time quietly starts costing it. AI transcription closes that gap. By converting speech to text the moment it’s recorded, it turns a disposable audio clip into a permanent, searchable, shareable piece of information — the raw material for real productivity, not just raw capture. What “AI Transcription” Actually Means in 2026 Transcription software has existed for decades, but the AI transcription of 2026 is a different category of tool. Early speech-to-text engines struggled with accents, background noise, and overlapping speakers, and the output was often a wall of text nobody wanted to read. Today’s models, trained on far larger and more diverse audio datasets, handle natural, messy, real-world speech — including filler words, code-switching between languages, and multiple speakers in the same recording. A few developments define the current generation of tools: Put together, these features mean transcription is no longer just “audio turned into text.” It’s the first processing layer of a personal knowledge system — the step that makes everything you say as useful as everything you type. The Journey: From a Raw Voice Note to an Actionable Insight It helps to think of the process as a pipeline with four distinct stages. Understanding each one makes it much easier to choose the right tool and build habits that stick. 1. Capture This is the easy part most people already do well: recording a thought on a phone, a smart watch, or a dedicated voice recorder during a walk, commute, or meeting. The goal at this stage is simply to get the idea out of your head before it disappears — no editing, no structure, no second-guessing. 2. Convert The recording is uploaded or synced to an AI transcription tool, which converts speech into accurate, punctuated, speaker-labeled text within minutes. This is where tools like TrulyScribe do the heavy lifting: audio and video files are processed automatically, with support for a very wide range of languages and accents, so the transcript is usable the moment it’s ready rather than needing manual cleanup. 3. Condense Raw transcripts, especially from longer recordings, are still a lot to read. The condensing stage uses AI to pull out the signal from the noise — summarizing the recording into a short overview, highlighting decisions and action items, and organizing rambling thoughts into a clear structure. This is the stage that turns a five-minute voice note into three usable bullet points. 4. Convert to Action The final stage moves the condensed text out of the transcription tool and into wherever work actually happens: a task added to a to-do list, a line copied into an email draft, a decision logged in a project doc, or a follow-up scheduled on a calendar. This is the step that closes the loop — the moment a voice note stops being a recording and becomes something done. Most people skip stages two through four entirely and stay stuck at stage one, which is exactly why voice notes pile up unused. A good AI transcription workflow automates stages two and three so that stage four takes seconds instead of minutes. Where This Actually Helps: Everyday Use Cases AI transcription for personal productivity isn’t a niche, professional-only tool anymore. It shows up in dozens of small, practical moments across a week. What connects all of these is the same underlying shift: speech becomes data. Once a thought exists as text, it can be searched, tagged, summarized, translated, and moved into any other tool — something that’s simply not possible with a locked audio file. What to Look For in an AI Transcription Tool Not all transcription tools are built for personal productivity in the same way. Some are optimized for enterprise call centers, others for podcast editing. If your goal is turning everyday voice notes into action, a few features matter more than the rest. TrulyScribe is built around exactly this use case: unlimited AI-powered audio and video transcription with support for a very wide range of languages, automatic speaker labeling, timestamps, and export options that include DOCX and PDF, all wrapped in a straightforward editor where the transcript can be checked against the original audio in real time. For anyone trying to turn a habit of voice notes into an actual productivity system, that combination of speed, accuracy, and flexible export is what makes the difference between a tool you try once and one you use every day. Building a Voice-First Productivity System Having the right tool is only half the equation. The other half is a light structure around how you use it,

text-based-video-editing-workflow-post-production
Freelance Growth, Post-Production, Video Transcription

The Text-Based Video Editing Workflow: Scale Post-Production Output

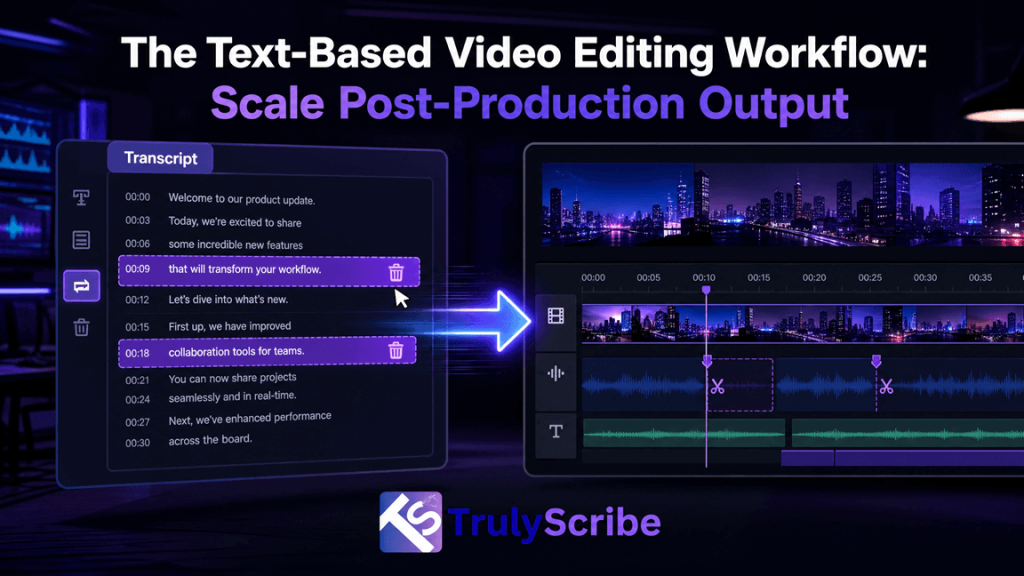
The most frustrating bottleneck in video editing isn’t color grading, complex motion graphics, or sound design. It’s the tedious, manual grind of digging through hours of talking-head footage, documentaries, corporate interviews, or zoom calls just to find a single missing quote or build a cohesive narrative. For solo freelance video editors and post-production subcontractors, this time sink directly limits income. When billing clients per project, hours spent scrubbing back and forth across a timeline to sync talking points are completely unbillable. The industry has moved beyond this bottleneck. By shifting to a text-based video editing workflow, you can treat raw footage like a text document—cutting, searching, and organizing an initial rough cut in minutes instead of days. What is a Text-Based Video Editing Workflow? A text-based video editing workflow replaces manual timeline scrubbing with interactive, timecoded transcription. Instead of tracking audio waveforms visually or listening to files at double speed, the entire video is converted into text. The Core Shift: Editing text automatically edits the video timeline. When you delete a sentence from the transcript, the linked video clip is trimmed instantly. When you search for a concept, the playhead jumps directly to that frame. For freelancers working as subcontractors for agencies, production companies, or corporate clients, this workflow bridges the gap between raw footage and a tight paper edit (a script built out of transcript components before heavy software editing begins). Why Manual Scrubbing is Killing Your Freelance Profit Margins Consider a standard project: a client delivers three separate 45-minute raw corporate interviews and requests a tight, 3-minute promotional highlight reel. Under a traditional manual post-production workflow, the time breakdown looks grim: Post-Production Stage Traditional Workflow Text-Based Workflow Initial Review 135 minutes (Watching footage at 1x speed) 0 minutes (Automated parsing) Logging & Timestamps 90 minutes (Typing out notable quotes) 5 minutes (TrulyScribe automated export) Rough Cut Assembly 120 minutes (Slicing, grouping, closing gaps) 15 minutes (Text-selection compilation) Client Review Prep 30 minutes (Adding temporary subtitles) 2 minutes (Automated SRT integration) Total Administrative Time 375 minutes (6.25 hours) 22 minutes Using manual methods, you waste nearly a full working day on organizational administration before you even touch creative assets like B-roll, pacing, transitions, or sound layers. A text-based editing approach completely reclaims these lost billable hours. Step-by-Step Blueprint: The Text-Based Post-Production System To get the full time-saving benefit, you need to decouple the initial narrative structuring from your heavy Non-Linear Editor (NLE) software like Adobe Premiere Pro, DaVinci Resolve, or Final Cut Pro. Step 1: Batch-Upload Raw Footages to TrulyScribe Do not immediately import massive, unorganized multi-gigabyte source video files directly into your primary video editing timeline. This bogs down your computer’s local processing performance and clutters your software media workspace. Instead, run your raw multi-speaker files through TrulyScribe first. The platform processes raw files rapidly in the cloud, generating highly accurate, time-stamped text files complete with clear speaker differentiation. Step 2: Perform the “Paper Edit” Digitally Once the transcript populates, review the text. Use the search functions to find primary talking points, key phrases, or thematic responses. Step 3: Align the Transcript to the NLE Timeline Import your raw source video footage into your choice of desktop NLE (Premiere Pro, DaVinci, or Final Cut). Instead of guessing where edits should go, open your exported, timestamped TrulyScribe script on a secondary monitor. Because the script explicitly dictates where the best narrative arcs begin and end down to the exact second (e.g., [00:14:22 – 00:14:45]), you can snap your blade tool precisely to those timeline positions on your first pass. Step 4: Rapid Assembly of the Rough Cut With your text blueprint guiding your actions, perform a rapid extraction pass. Splice the selected audio segments out, push them together into a unified sequence line, and strip out the dead space. You now have a clean narrative spine ready for your primary creative additions: dropping relevant secondary B-roll over jump cuts, balancing dialogue tracks, color matching, and mastering final audio components. Advanced Subcontractor Techniques: Managing Remote Clients Asynchronously If you work as a freelance subcontractor for creative agencies, your greatest friction point is often the client review phase. Clients frequently send vague revision notes like “Can we change that middle quote to something that sounds a bit more punchy?” Instead of opening your NLE and hunting blindly for alternative clips, use your transcript assets to manage client communication completely asynchronously: FAQs: Text-Based Video Editing Workflows

best-ai-transcription-tools-json-srt-export-video-editing
AI Tools, Transcription Software, Video Editing

Best AI Transcription Tools That Support JSON and SRT Export for Video Editing

A practical 2026 buyer’s guide for video editors, agencies, and dev teams who need caption-ready SRT files and developer-ready JSON in the same workflow. If you edit video for a living, a transcript alone isn’t enough anymore. You need an SRT file to drop captions straight onto your timeline, and you increasingly need a JSON export with word-level timestamps to power text-based editing, custom caption styling, or an automated publishing pipeline. Choosing a transcription tool that only gives you one of these formats means someone on your team ends up hand-converting files or writing a script to bridge the gap — a workflow tax most editors don’t have time for. We looked at the AI transcription tools that reliably export both SRT and JSON (not just one, buried behind an enterprise tier), and evaluated them on accuracy, speaker labeling, language coverage, and how easily the export actually plugs into a real editing workflow. Here are the seven best options in 2026, starting with the tool that makes JSON-to-SRT workflow integration the least painful. Why SRT and JSON Together Actually Matter SRT (SubRip Text) is the caption format every platform and editor understands — YouTube, Vimeo, Premiere Pro, DaVinci Resolve, Final Cut, and CapCut all ingest it natively. It’s the format you need the moment a video needs subtitles. JSON is different. Instead of just timed caption blocks, a JSON transcript gives you structured, word-level timestamps, speaker labels, and confidence scores — the raw data that powers text-based video editing (delete a word, the clip cuts), karaoke-style animated captions, searchable transcript archives, and automated publishing pipelines that push captions into a CMS or app without a human touching a file. A tool that hands you only SRT leaves your dev or automation team stuck writing a parser. A tool that hands you only JSON leaves your editor stuck hand-building caption files. The tools below give you both, so the same transcription job can serve your publishing workflow and your engineering workflow at once. 1. TrulyScribe — Best Overall for Workflow Integration TrulyScribe tops this list because it’s built around the handoff problem most teams actually run into: one file for the editor, one format for the pipeline. From a single upload, TrulyScribe generates a full transcript with speaker labels and timestamps, then lets you export straight to SRT for captions, alongside structured JSON output through its API for teams building automated editing or publishing pipelines. That means your video editor can pull a caption-ready SRT for Premiere or YouTube in the same job that your dev team pulls a timestamped JSON payload for a custom captioning tool or CMS integration — no separate vendor, no manual conversion step. Beyond format flexibility, TrulyScribe is built for the parts of a real production workflow that slow teams down: bulk upload for processing multiple episodes or clips at once, accurate speaker identification for multi-speaker interviews and panels, and support for 100+ languages and dialects for teams localizing content. Files are encrypted in transit and at rest and the platform is GDPR-compliant, which matters for agencies handling client footage. Best for: video editing teams, content agencies, and product teams that want one platform to cover both the caption-and-publish side of the workflow and the automation-and-integration side — without stitching together two separate tools. 2. Sonix Sonix is a strong all-around pick for teams that need enterprise-grade accuracy alongside flexible exports. It supports transcript and subtitle export in SRT, VTT, and JSON, with native integrations into Premiere Pro, Final Cut Pro, Zoom, and YouTube, plus a developer API for teams that want to build transcription into their own tools. Its compliance profile (SOC 2 Type II, HIPAA-ready workflows) makes it a common choice for legal, healthcare, and enterprise media teams handling sensitive recordings. Best for: enterprise and compliance-conscious teams that need wide language coverage and NLE integrations alongside JSON access. 3. Descript Descript is less a transcription tool and more a video editor built on top of one — you edit the video by editing the transcript text, and deleting a word cuts the corresponding clip automatically. It exports captions as SRT/VTT and exposes timestamped transcript data through its API for teams that want to build on top of it. If your team wants transcription and rough-cut editing in the same interface, Descript is the strongest single-tool option, though it leans more expensive than dedicated transcription platforms. Best for: podcasters and video producers who want transcription and text-based editing bundled into one app. 4. Happy Scribe Happy Scribe pairs AI transcription with an optional human-proofreading layer, which makes it a good fit for teams that need occasional guaranteed accuracy on top of fast AI drafts. Its browser-based editor exports to SRT, VTT, DOCX, and JSON, with support for 120+ languages — one of the widest ranges on this list — making it a solid option for global subtitle and localization workflows. Best for: video production teams and localization teams that need multilingual subtitle exports with an optional human QA step. 5. ElevenLabs Scribe ElevenLabs’ transcription tool exports to a genuinely wide format list — TXT, DOCX, PDF, JSON, HTML, SRT, and VTT — straight from the same job, with word-level timestamps and speaker labels for up to 32 speakers. It also tags non-speech audio events like laughter or applause, which is a useful detail for documentary or interview editors trying to avoid losing context in the transcript. Language coverage is broad, with accurate results claimed across 99 languages. Best for: creators and editors who want maximum export-format flexibility from one transcription pass. 6. AssemblyAI AssemblyAI is a developer-first speech-to-text API rather than a dashboard product, which makes it the right pick for engineering teams building their own transcription or captioning feature into a video platform or app. Output is native JSON with word-level timestamps and speaker diarization; SRT/VTT generation is handled through the API rather than a one-click export button. It’s priced per minute of audio processed, which tends to be far cheaper than subscription

ai-transcription-qualitative-data-analysis-2026
AI Transcription, Qualitative Research, Research Tools

Unlocking Insights: Using AI Transcription for Qualitative Data Analysis (QDA) in 2026

If your qualitative research pipeline still starts with hours of manually typing out interviews and focus groups, 2026 is the year to change that. Qualitative Data Analysis (QDA) has always promised rich, human insight — the kind numbers alone can’t deliver. But that richness has a cost: every hour of recorded conversation traditionally took four to six hours to transcribe by hand before analysis could even begin. AI transcription has quietly rewritten that equation, and researchers who haven’t adopted it yet are leaving both time and insight on the table. In this guide, we’ll look at why AI transcription has become foundational to modern QDA, how it fits into a real research workflow, and how tools like TrulyScribe help researchers move from raw audio to coded themes faster, more accurately, and more securely. What Is Qualitative Data Analysis, and Why Does Transcription Matter So Much? Qualitative Data Analysis is the process of systematically examining non-numerical data — interviews, focus groups, open-ended survey responses, field recordings — to identify patterns, themes, and meaning. Unlike quantitative analysis, QDA depends on close reading: researchers need to sit with the actual words participants used, not just a summary of them. That’s exactly why transcription sits at the center of the QDA workflow. Every coding scheme, every theme map, every quote you pull for a report starts with an accurate, searchable text version of your audio or video. If the transcript is wrong, incomplete, or missing who said what, the analysis built on top of it inherits those flaws. Transcription isn’t a clerical afterthought in qualitative research — it’s the foundation everything else stands on. Why AI Transcription Has Become Essential for QDA in 2026 A few years ago, AI transcription was a convenience. Today, it’s close to a prerequisite for any research team that wants to stay competitive on turnaround time without sacrificing rigor. A few shifts explain why: 1. Accuracy Has Reached Research-Grade Levels Modern AI transcription engines now regularly achieve accuracy rates upward of 99% on clear audio, and they handle accents, overlapping speech, and domain-specific vocabulary far better than earlier speech-to-text models. TrulyScribe, for example, is built around 99.8% accuracy, which means researchers spend their time reviewing edge cases rather than re-typing entire sessions. 2. Speaker Labeling Turns Audio Into Analyzable Dialogue Focus groups and multi-participant interviews are where manual transcription becomes painful — someone still has to track who said what. AI transcription with automatic speaker labels does this in real time, giving researchers a transcript that’s already structured for coding by participant, not just a wall of undifferentiated text. 3. Timestamps Keep Transcripts Tied to Original Context Good QDA often requires going back to the original recording — to check tone, hesitation, or emphasis that text alone can’t capture. Timestamped transcripts let researchers jump straight to the relevant moment in the audio or video instead of scrubbing through an hour-long file to find one quote. 4. Multilingual Research No Longer Requires a Bigger Team Cross-cultural and international studies used to require hiring transcribers fluent in each language. AI transcription platforms that support dozens of languages let a single researcher process interviews from multiple regions without waiting on external vendors, which shortens the runway from data collection to analysis considerably. 5. It Frees Researchers for the Work That Actually Requires a Human Coding, theme development, and interpretation are the parts of QDA where a researcher’s judgment matters most. Automating the transcription step means more hours go toward that thinking work instead of data entry. A Practical AI-Assisted QDA Workflow for 2026 Here’s how AI transcription fits into a typical qualitative research project, from raw recording to finished analysis. Step 1: Record with the end analysis in mind. Use a decent microphone, minimize background noise, and where possible record each participant on a separate channel. Clean audio input is still the single biggest factor in transcript accuracy, AI or not. Step 2: Transcribe with an AI tool built for research use. Upload your audio or video files to a platform like TrulyScribe, which converts them to text with speaker labels and timestamps in a fraction of the recording’s runtime, and supports export in the formats most QDA software expects, including DOCX and PDF. Step 3: Review and lightly edit the transcript. Even at 99%+ accuracy, a quick pass matters — especially for names, acronyms, or technical terms specific to your study. Use the timestamped playback to verify anything ambiguous rather than guessing. Step 4: Import into your QDA software. Tools like NVivo, ATLAS.ti, MAXQDA, or Dedoose accept clean, speaker-labeled transcripts directly, letting you begin coding immediately instead of reformatting text first. Step 5: Code, theme, and synthesize. This is where human interpretation drives the analysis — grouping excerpts into codes, developing themes, and building the narrative or framework your research question calls for. Step 6: Pull verified quotes with confidence. Because your transcript is timestamped and speaker-labeled, every quote you cite in a report or publication can be traced back to its exact source and moment, which matters for both accuracy and research integrity. Key Benefits Researchers Are Seeing Addressing the Common Concerns “Can AI really handle messy, real-world audio?” Modern models handle a wide range of accents, cross-talk, and background noise far better than earlier generations of speech recognition. It’s not flawless — heavily overlapping speech or very poor audio quality will still need manual cleanup — but for the vast majority of interviews and focus groups, AI transcription now gets researchers 90-99% of the way there automatically. “What about participant confidentiality and data security?” This is a legitimate and important concern, especially for research involving sensitive topics or vulnerable populations. Look for a transcription provider with encrypted storage, secure processing, and clear data-handling policies — and check what your institution’s IRB or ethics board requires before uploading any identifiable data. Reputable platforms are built specifically with this kind of confidential, professional use case in mind. “Will it work for my niche field’s terminology?” Domain-specific vocabulary — medical terms,

mastering-multilingual-content-ai-transcription-2026
AI Transcription, Localization & Translation

Mastering Multilingual Content: AI Transcription for Global Audiences (2026)

Your next customer might not speak English. In 2026, that’s not a niche consideration — it’s the default. Most of the internet’s audience consumes content in a language other than English, yet most brands still produce content in just one or two languages and hope translation “happens eventually.” It rarely does, and when it does, it’s slow, expensive, and inconsistent. AI transcription has quietly become the fastest, most reliable starting point for going multilingual — not just for subtitles, but for blogs, SEO content, customer support documentation, and training materials. This guide breaks down exactly how AI transcription powers multilingual content workflows in 2026, what to look for in a tool, and how to avoid the mistakes that quietly tank localization quality. Quick answer: AI transcription converts spoken audio or video into accurate text in the original language, which then becomes the foundation for translation, subtitling, and localized publishing — turning one recording into content for every market you serve, in a fraction of the time manual processes take. Why Multilingual Content Matters More Than Ever in 2026 Three shifts have made multilingual content non-negotiable this year: The brands winning international audiences in 2026 aren’t necessarily the ones with the biggest content budgets. They’re the ones with the most efficient pipeline for turning one recording into many languages. The Multilingual Content Problem (Without AI) Here’s what going multilingual used to look like: Multiply that by five or six target markets, and a single piece of content can take weeks to localize — by which point it may no longer be relevant. This bottleneck is exactly why so many companies default to English-only content, even when they know it’s limiting their reach. How AI Transcription Powers Multilingual Content Workflows AI transcription doesn’t replace translation — it removes the single biggest bottleneck that comes before translation: getting clean, accurate, well-structured text out of audio or video in the first place. Step 1: Transcribe Once, in the Source Language Upload your recording — an interview, webinar, podcast episode, or product demo — and get a clean transcript with speaker labels and timestamps in minutes instead of hours. This becomes your single source of truth for every downstream language. Step 2: Translate and Localize at Scale With a clean transcript in hand, translation becomes dramatically easier — whether you’re using human translators, AI-assisted translation, or a hybrid review process. Translators work from organized, accurate text instead of re-listening to raw audio, which cuts turnaround time significantly and reduces costly misinterpretations. Step 3: Generate Multilingual Subtitles and Captions Once translated, transcripts can be exported as SRT files for subtitles, embedded directly into video platforms, or formatted for closed captions — giving every market a native-language viewing experience without re-editing the original video. Step 4: Repurpose Across Formats and Markets A single transcript, once translated, can become a blog post, a set of social captions, an email newsletter, or a help-center article — all localized, all without re-recording anything. One recording, many markets, minimal extra work. Key Features to Look for in a Multilingual AI Transcription Tool Not every transcription tool is built for global workflows. Here’s what actually matters: Feature Why It Matters for Multilingual Content Broad language and dialect support You need accuracy across the specific languages your audience speaks — not just major ones Speaker diarization Multilingual interviews and panels need clear speaker labels before translation begins Accurate timestamps Essential for generating subtitles and captions that stay in sync after translation Multiple export formats (TXT, DOCX, PDF, SRT) Different teams and platforms need different formats — subtitles, blogs, and documentation all use different files Data security and compliance Sensitive recordings — legal, medical, corporate — need encryption and privacy guarantees regardless of language Editable transcripts No AI transcript is translation-ready straight out of the box; easy in-platform editing saves real time Real-World Use Cases for Multilingual AI Transcription Multilingual SEO: Turning Transcripts Into Global Search Visibility Search engines can’t watch your video or listen to your podcast in any language — but they can crawl text. Publishing translated transcripts as on-page content gives every regional version of your site something to actually rank for. This is one of the most underused multilingual SEO tactics available: instead of writing separate localized articles from scratch, brands can publish translated, lightly edited transcripts as blog posts or landing pages, complete with locally relevant keywords pulled from the conversation itself. Common Challenges — and How AI Handles Them Multilingual transcription isn’t flawless, and it helps to know where the friction usually shows up: The fix isn’t avoiding AI transcription — it’s pairing it with a short human review step before content goes into translation, which still ends up far faster than fully manual processes. Best Practices for Multilingual Content Workflows in 2026 How TrulyScribe Helps You Go Global TrulyScribe’s AI transcription supports 100+ languages and dialects, with speaker diarization and accurate timestamps built in — the exact foundation a multilingual content pipeline needs. Transcripts export straight to TXT, DOCX, PDF, or SRT, so the same transcript can move into translation, subtitle work, or a CMS without reformatting. And because recordings often include sensitive client, legal, or corporate conversations, every file is encrypted in transit and at rest, with GDPR-compliant processing built in by default. For teams creating content across multiple markets, that means one upload — and a transcript that’s ready to become five different languages of content. FAQs: AI Transcription for Multilingual Content Final Thoughts Going multilingual used to mean choosing between speed and quality — fast translations that felt rough, or polished ones that took weeks. AI transcription removes that trade-off at the source: a clean, accurate, well-organized transcript turns translation, subtitling, and localized publishing from a bottleneck into a repeatable workflow. In 2026, the brands reaching global audiences aren’t necessarily recording more content — they’re getting more languages out of the content they already have.

ai-transcription-podcasters-advanced-seo-engagement
AI Transcription, Podcasting & Audio Production, SEO & Content Marketing

AI Transcription for Podcasters: Advanced Strategies for SEO & Engagement (2026)

Most podcasters who discover AI transcription use it the same way: get the transcript, publish it on the episode page, feel good about the accessibility box being ticked, and move on. That’s a start. But it’s also leaving most of the value on the table. Transcripts are not just a convenience feature or an accessibility compliance tool. In 2026, they are the most underutilised growth lever available to independent podcasters. A single well-executed transcript strategy can triple your organic search traffic, generate eight or more pieces of original content from one episode, earn backlinks from publications that would never link to an audio file, and build the kind of audience engagement that turns casual listeners into loyal subscribers. This guide is for podcasters who already know the basics — or who want to skip past them entirely. It covers the advanced strategies: how to structure transcripts for SEO dominance, how to use them for answer engine optimisation, how to build a content repurposing system that runs on autopilot, how to design engagement loops that transcripts power, and how to monetise the content assets that transcription creates. These are not theoretical strategies. They are the approaches that consistently-growing podcasts use to build audiences and income at a scale that audio-only distribution alone cannot achieve. Why Most Podcasters Are Underusing Their Transcripts The typical podcast transcript workflow looks like this: transcribe the episode, paste the text into a collapsible section on the episode page, label it “Transcript,” and publish. Done. This approach captures perhaps 10 to 15% of the available value from transcription. The remaining 85 to 90% — the SEO compound effect, the content repurposing potential, the engagement infrastructure, the monetisation opportunities — is left entirely unrealised because the transcript is treated as a document to archive rather than a content engine to activate. 72%  of podcast episodes have no published transcript — a competitive gap for podcasters who do 3x  more organic traffic earned on average by podcast episode pages with structured published transcripts vs audio-only pages 47  average number of long-tail keywords a single 45-minute podcast episode transcript ranks for within 90 days of publishing The gap between what most podcasters do with transcripts and what the most sophisticated podcasters do is the gap this guide is designed to close. Part 1: Advanced Transcript SEO — Turning Episodes into Search Traffic The SEO opportunity in podcast transcription is one of the least contested in digital marketing. Most of your competitors are not doing this. The ones who are, are not doing it well. The window to build a significant organic search advantage through podcast transcript SEO is still wide open in 2026. The SEO Foundation: Why Transcripts Are a Search Traffic Machine Audio is invisible to search engines. Every insight, every expert quote, every keyword-rich exchange in your podcast exists in a format that Google cannot read, index, or rank. Publishing a transcript changes that entirely. A 45-minute podcast episode contains approximately 6,000 to 8,000 words of natural language content. Published as a structured transcript, that content: The Advanced Transcript SEO Strategy Matrix SEO Strategy How Transcripts Enable It Expected Impact Long-tail keyword targeting Transcript text naturally covers hundreds of related queries Rank for queries you never explicitly targeted Featured snippet capture Q&A sections in transcripts match question-format queries Position 0 for “how to” and “what is” searches Topical authority building Library of transcripts on related themes signals expertise Higher domain authority and cluster rankings Internal linking Cross-link between transcripts covering related topics Better crawl depth and topic coherence signals Backlink acquisition Written content earns 3x more links than audio-only pages Domain authority growth from editorial links Video SEO (YouTube) .srt captions from transcript improve video search rank Higher YouTube CTR and watch time from captions Answer engine optimisation Transcripts provide structured text for AI answer sources Citations in Perplexity, ChatGPT, Gemini responses Strategy 1: Keyword Cluster Architecture The most sophisticated podcasters don’t publish transcripts in isolation — they build keyword cluster architectures where each episode transcript targets a specific keyword cluster within their niche, and all clusters link back to pillar content pages. Here’s how to implement this: 💡  SEO compounding effect:  A topic cluster architecture means that as you publish new episode transcripts, every new piece adds authority to the entire cluster. A podcast with 50 episodes in a tight niche, all interlinked through a cluster architecture, can build topical authority that rivals dedicated niche websites with far fewer episodes. Strategy 2: Featured Snippet Optimisation Featured snippets — the answer boxes that appear at position zero in Google results — are disproportionately valuable for podcasters because they capture search traffic before a user even clicks a result. Podcast transcripts are unusually well-suited to earning featured snippets for a specific reason: the conversational Q&A structure of most podcast episodes. When a host asks a guest “What is the single most important thing a new podcaster should do?” and the guest gives a clear, structured answer, that exchange is almost exactly what Google looks for to populate a featured snippet. The question matches a user search query; the answer is the snippet content. How to optimise transcript content for featured snippets: Strategy 3: Answer Engine Optimisation (AEO) In 2026, search behaviour has shifted significantly toward AI-powered answer engines. When someone asks Perplexity, ChatGPT Search, Google’s AI Overview, or Gemini a question in your niche, the answer they receive is assembled from sources that the AI can read, cite, and trust. Audio cannot be cited. Transcripts can. Answer engine optimisation (AEO) is the practice of structuring your content specifically to be cited by AI answer systems. Podcast transcripts are a natural fit for AEO because they contain expert opinion, specific facts, and conversational explanations in a format that AI systems can extract and summarise. AEO strategies for podcast transcripts: Strategy 4: YouTube SEO via Transcript Captions If you publish a video version of your podcast — or even a simple static image video for YouTube distribution — your transcript

AI Transcription, Engineering & Science, How-To Guides, Professional Use Cases

Transcribing Technical Jargon: AI Solutions for Engineering & Scientific Meetings (2026)

Ask any engineer or research scientist what they do after a complex technical meeting and the answer is almost always the same: spend the next 30 minutes trying to reconstruct what was discussed from a combination of hurried notes, half-remembered decisions, and a growing anxiety that the most important detail was the one they didn’t write down. Technical meetings are among the most information-dense conversations that happen in any organisation. A 60-minute design review might cover materials selection with specific tolerance values, software architecture decisions referencing particular framework versions, test protocols with precise procedural steps, and cross-disciplinary debates where three different teams are each using their own vocabulary for the same concept. The person responsible for writing the meeting notes is simultaneously trying to follow the technical argument, understand its implications, and capture it accurately — an impossible multi-task under any conditions. AI transcription has become a practical tool for engineering and research teams in 2026. But the question these teams ask more than any other is: can it actually handle our vocabulary? Our acronyms? Our model names and compound identifiers and IUPAC notation? The honest answer is: better than you expect, with some important caveats — and with the right review workflow, extremely well. This guide covers everything technical teams need to know about using AI transcription for complex meetings in 2026: where it works, where it struggles, how to prepare for technical vocabulary, and the review workflow that maximises accuracy for high-stakes technical documentation. Why Technical Meetings Are Especially Hard to Document Technical meetings have a unique documentation challenge that goes beyond simple note-taking difficulty. Several compounding factors make them particularly hard to capture accurately: Density of specialised vocabulary A typical engineering or research meeting might contain dozens of acronyms, product identifiers, chemical compound names, model designations, and standard references that have no meaning outside a specific discipline or even a specific project. An AI transcription model trained on general-purpose speech has seen a broad vocabulary — but it may not have encountered the specific combination of terms that makes your team’s meetings unique. This is the single most important factor in AI transcription accuracy for technical teams, and it is also the most addressable with the right preparation workflow. Phonetically ambiguous terminology Technical language is full of terms that sound similar to common words or to each other. An AI model hearing “FPGA” for the first time in context might render it as “EF-PGA” or something phonetically similar but wrong. A compound like “CMOS sensor” might be heard as a common word combination that makes contextually plausible but technically incorrect sense. Single-letter prefixes on SI units (milli-, micro-, nano-) can be lost or confused in fast speech. Multi-discipline team vocabulary divergence Cross-functional technical meetings — a software architect, a mechanical engineer, a project manager, and a client stakeholder all in the same call — involve participants using different vocabularies for the same concepts. The software engineer says “latency,” the mechanical engineer says “response time,” and the client says “lag.” An accurate transcript preserves what each person actually said; a bad set of notes homogenises these distinctions away. High-stakes accuracy requirements In engineering and science, inaccuracy in documentation is not a minor inconvenience — it can have material consequences. A misrecorded tolerance value in a design review transcript. A wrong version number in a software architecture decision record. A confused chemical notation in a lab debrief. These are not typos; they are potentially significant errors that need to be caught and corrected before the document is relied upon. This is why AI transcription for technical teams requires a more structured review process than transcription for general business meetings — and why understanding what AI handles well vs what requires specific human review is critical. 6–10 hrs  per week that the average engineer or scientist spends on manual note-taking, documentation, and meeting follow-up 40%  of action items from technical meetings are not completed because they were not accurately captured in meeting notes 90–95%  baseline accuracy of modern AI transcription on clear audio — even for technical content with specialist vocabulary Technical Jargon by Discipline: What AI Transcription Faces Discipline Typical Jargon Challenges Examples AI Must Handle Mechanical Engineering Material specs, tolerance notation, CAD tool names GD&T, ANSI/ISO standards, FEA, CNC, SPC Software Engineering Framework names, version strings, acronym-heavy protocols CI/CD, Kubernetes, GraphQL, REST API, OAuth 2.0 Electrical Engineering Component identifiers, circuit terminology, unit prefixes MOSFET, PWM, ADC, FPGA, BJT, THD, EMI/EMC Biomedical / Life Sciences Latin nomenclature, gene symbols, assay names CRISPR-Cas9, PCR, ELISA, mRNA, VEGF, qRT-PCR Chemistry / Materials Science Compound names, IUPAC notation, reaction types XRD, SEM-EDX, TGA, PDMS, ZnO nanoparticles Aerospace & Defence System designations, MIL-SPEC codes, test protocols MIL-STD-461, ARINC 429, DO-178C, ADS-B, TRL Data Science / AI Research Model architectures, metric names, framework terms LSTM, transformer, BLEU score, PyTorch, fine-tuning Environmental / Earth Science Measurement protocols, species nomenclature, GIS terms NDVI, LiDAR, Sentinel-2, GHG flux, VOC, PM2.5 * The examples above are illustrative of common terminology types by discipline. AI transcription accuracy on specific terms varies based on audio quality, accent, and whether terms appear in the training corpus. The glossary workflow described later in this guide addresses terms that the AI may not handle correctly by default. What AI Transcription Handles Well in Technical Meetings Before addressing the limitations, it’s important to be accurate about what modern AI transcription does well in technical contexts — because the starting point is significantly stronger than most engineers and scientists expect. Widely-used technical terminology AI transcription models are trained on enormous corpora of text and audio, including a large proportion of technical and scientific content. Widely-used acronyms and terms from major disciplines are well-represented in training data. Terms like API, CPU, machine learning, RNA sequencing, finite element analysis, Agile, neural network, spectroscopy, and hundreds of others from mainstream engineering and science disciplines are transcribed accurately in the vast majority of cases. The challenge arises with niche or project-specific terminology, not with the broad technical vocabulary

Scroll to Top